Meituan’s official LongCat-2.5 drop: 1.6T/~48B native multimodal agent—API live, weights not
Terminal Bench v4.0 jumps from 3.0 (2.0) to 38.5; BrowseComp 91.9 tops their table; 10M signup tokens, cache hits free
@Meituan_LongCat posted at 2026-11-02 14:35 UTC (22:35 Beijing): LongCat-2.5 is out—a natively multimodal MoE with 1.6T total parameters and ~48B active, aimed at long-horizon agentic work, with stronger visual understanding and agentic coding across complex projects, creative design, and 3D. Within about an hour the post was past 600 likes and 100 bookmarks. The technical blog is dated 2026-11-01; the API changelog stamps 2.5 as available the same calendar day as the X announce.
Two misreads to kill early. First, third-party posts circulated earlier today—those were leaks/previews, not the official launch. This piece tracks the official X thread, the tech blog, and the API platform. Second, do not import LongCat-2.0’s “weights on day one” habit: Hugging Face’s meituan-longcat org still lists 2.0 and the Flash line, not 2.5; GitHub has no 2.5 weights repo either. Availability right now is Chat + API. Weights are not public.
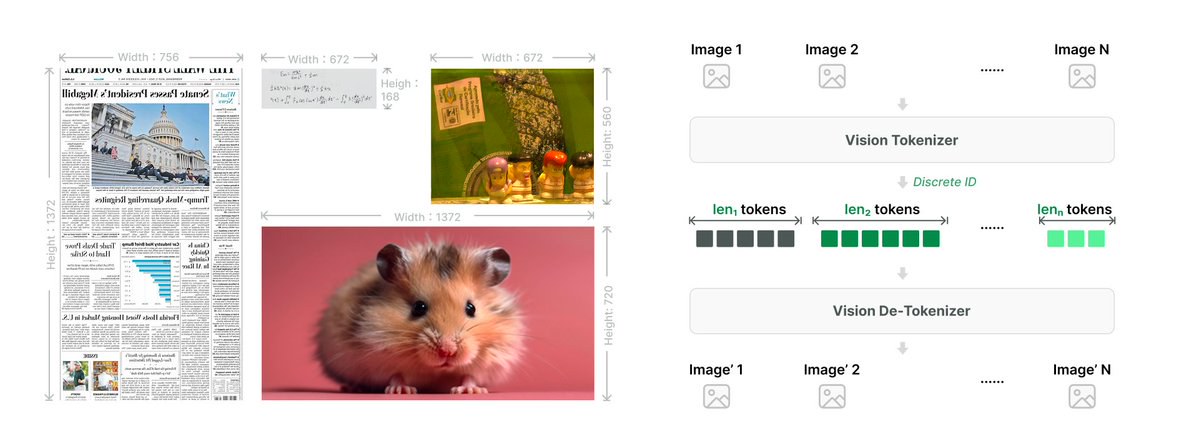
The size card is unchanged from 2.0; the capability bet is not. Training packs more long-horizon trajectories and large-scale long-horizon RL, and turns real agent failure traces into reproducible, verifiable tasks. Vision is multi-level discrete tokens via RVQ on SAE features, so the backbone eats image and text in one token format; a fixed tokenizer lets visual IDs be precomputed and cached offline, and the vision encoder drops out of the training graph. The product page also claims harness compatibility with Claude Code, Codex, Hermes, and peers.
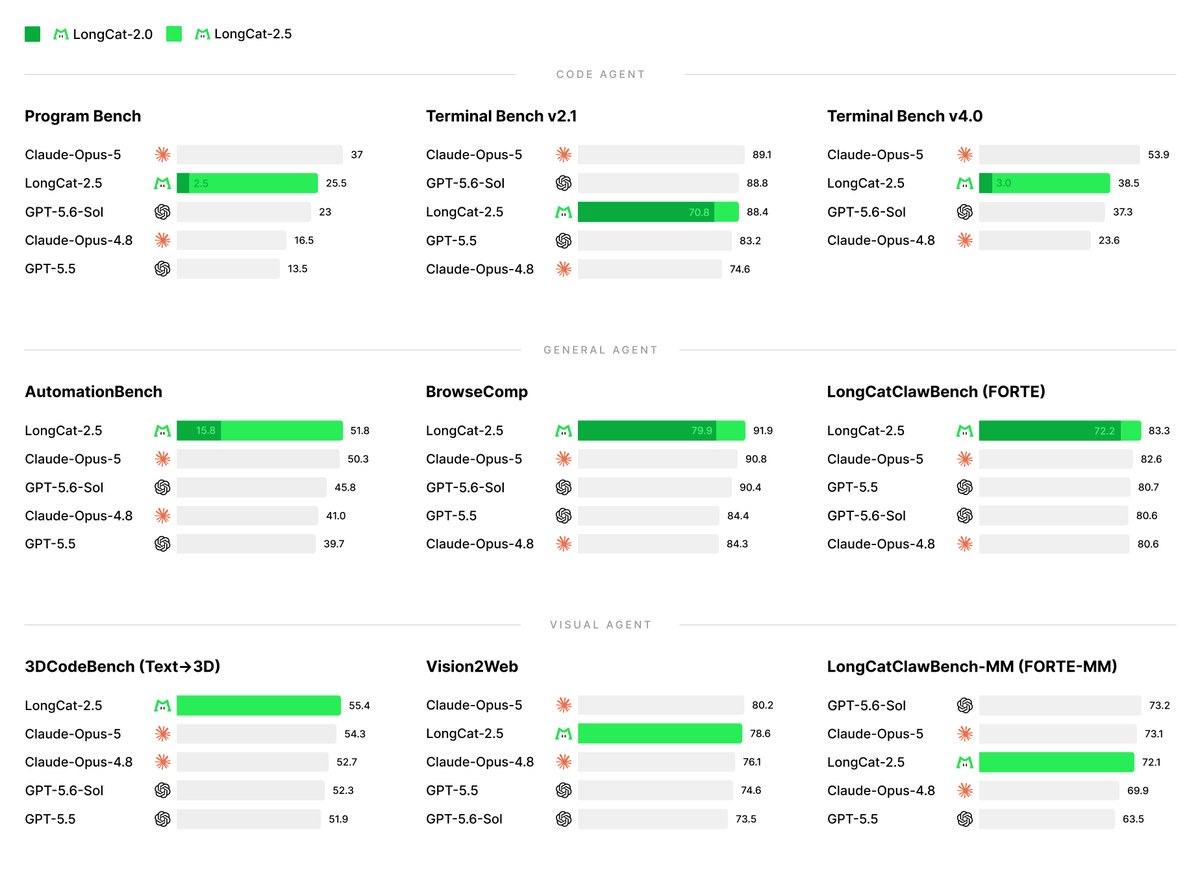
The evaluation table is the expert-readable core. Against GPT-5.5, GPT-5.6-Sol, Claude-Opus-4.8, Claude-Opus-5, GLM-5.3, kimi-k3, and DeepSeek-V4.1-Flash, the numbers that matter:
- Terminal Bench v4.0: 38.5 (2.0 was 3.0; Opus-5 53.9; GPT-5.6-Sol 37.3)
- Terminal Bench v2.1: 88.4 (2.0 was 70.8; within a point of Opus-5’s 89.1 and Sol’s 88.8)
- Program Bench Almost Resolved: 25.5 (2.0 was 2.5)
- BrowseComp: 91.9 — highest in their table
- AutomationBench v1.0.6: 51.8 — highest in their table
- 3DCodeBench Text→3D: 55.4 — highest in their table
- DeepSWE v1.1: 64.6 — soft side of the peer set (Sol 72.7; DeepSeek-V4.1-Flash 74.2)
- Vision2Web: 78.6 (Opus-5 80.2)
Long-horizon engineering is the step-change versus 2.0; browse/automation tasks can lead the board; deep SWE still trails. Read the footnotes: LongCat-2.5 runs with enable_thinking=on, temperature 1.0, top_p 0.95; starred competitor scores come from public reports or leaderboards, unstarred ones are Meituan self-runs labeled indicative; harnesses differ (Claude Code, mini-swe-agent, Codex, custom browse harness). The comparison set also omits newer GPT-6 / Opus-5.5-class systems.
Infrastructure copy is domestic-accelerator flavored: long-sequence training under <80 GB per card, supernode-aware FSDP claimed at +86% per-device throughput vs a DDP baseline; W4A4 inference (expert weights and activations at 4-bit) posts +43.3% prefill and +42.77% decode vs W8A8 in stress tests, with TTFT / TPOT down 15.91% / 19.72%. End-to-end showcases span real-time fluid simulation, 3D exhibitions, city dioramas, business ops analysis, and feedback reports. The announce media set is a brand key visual, a nine-panel benchmark bar chart, and a native-resolution vision-tokenizer schematic.
API is live. Docs list LongCat-2.5 as the supported model, with OpenAI-compatible (https://api.longcat.chat/openai) and Anthropic-compatible (https://api.longcat.chat/anthropic) endpoints; per-request limits are a 1M-token context and 128K max output. The announce thread’s follow-up: 10 million tokens on signup, another 10 million for existing users, auto-credited, cache hits free. Limited-time pay-as-you-go (platform page authoritative): uncached input $0.30 / 1M tokens, cached input $0.006, output $1.20 (CNY board ¥2 / ¥0.04 / ¥8). Token Pack FAQ restates that cache hits do not burn pack quota.
For people who live in agent stacks, LongCat-2.5 is not “another trillion MoE.” It is Meituan shipping long-horizon RL + discrete native vision + multi-harness mixed training as a callable product—and deliberately opening the service before the weights. To check the numbers today you run Chat/API yourself. For local weights, wait until a real 2.5 repo appears on HF/GitHub—do not hallucinate 2.0’s open-source cadence onto this release.