
Post-Training Generative Recommenders with Advantage-Weighted Supervised Finetuning
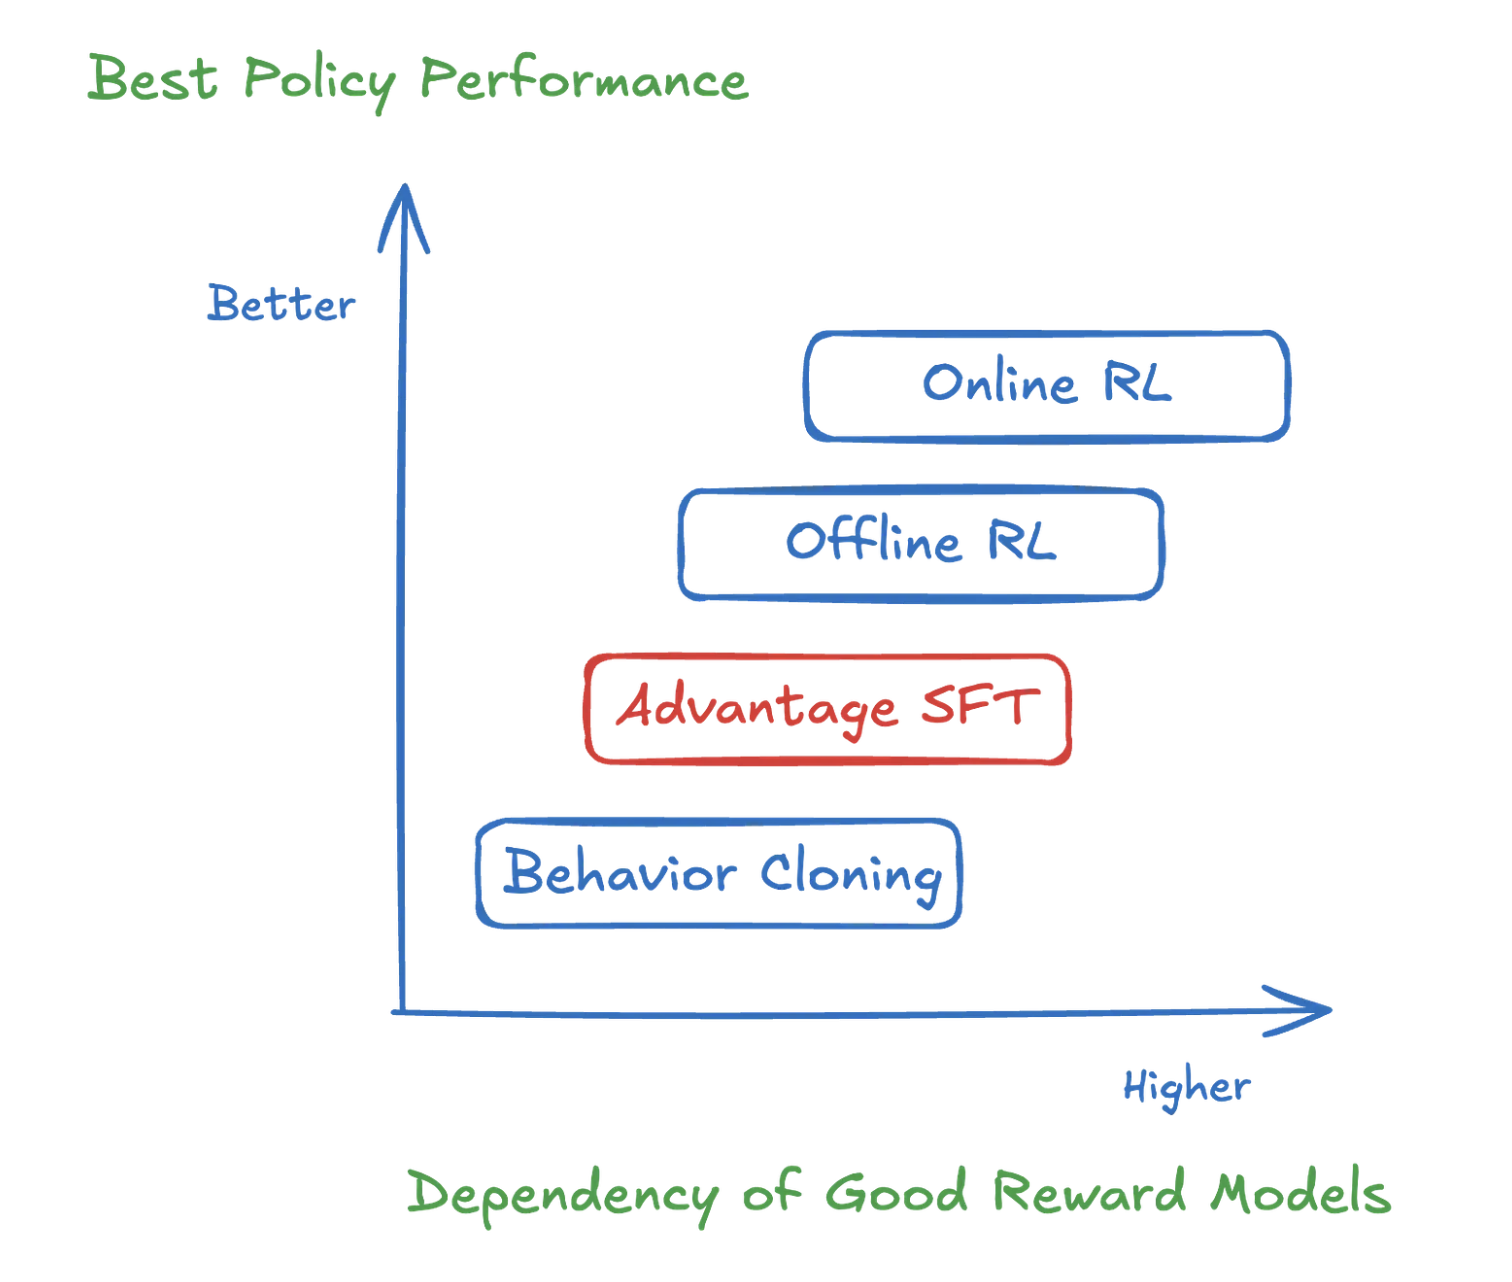
Generative recommender systems (GRs) leverage transformer architectures to model user behavior as a sequential prediction task, but simply imitating observed actions often fails to capture true user preferences due to noisy and limited feedback.
We investigate the use of post-training reinforcement learning (RL) techniques for GRs and identify key challenges, including the lack of counterfactual data and unreliable reward signals. To address these, we propose Advantage Supervised Fine-tuning (A-SFT), which combines supervised learning with RL’s advantage function to robustly utilize noisy rewards.
Experiments show A-SFT outperforms existing post-training methods, offering a practical and effective approach for improving generative recommenders.