
Switching the Loss Reduces the Cost in Batch Reinforcement Learning
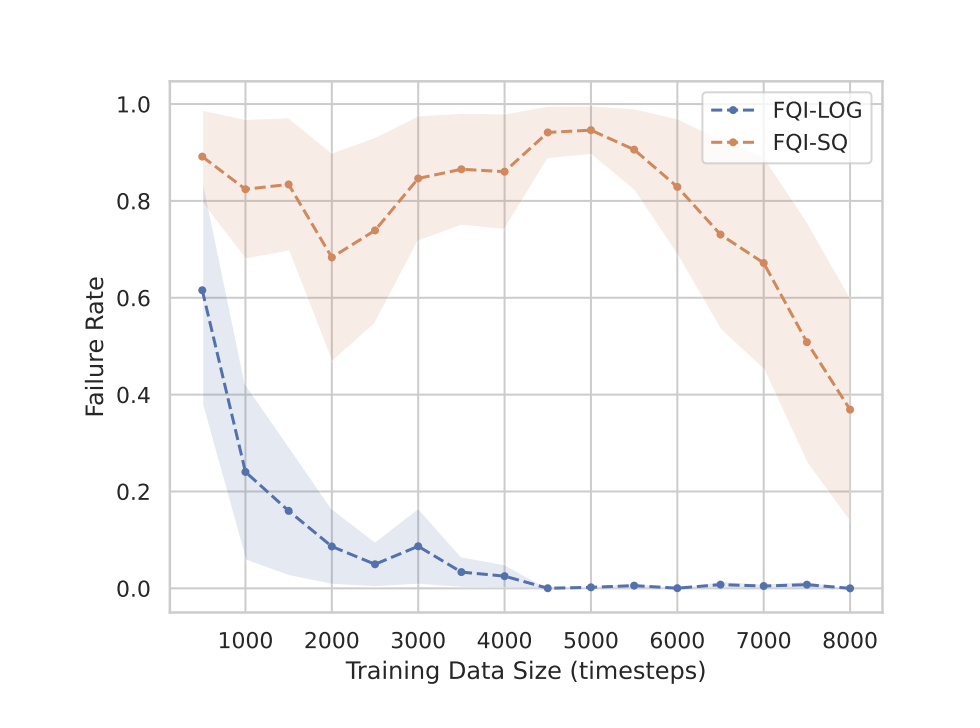
We propose training fitted Q-iteration with log-loss (FQI-LOG) for batch reinforcement learning (RL).
We show that the number of samples needed to learn a near-optimal policy with FQI-LOG scales with the accumulated cost of the optimal policy, which is zero in problems where acting optimally achieves the goal and incurs no cost.
In doing so, we provide a general framework for proving small-cost bounds, i.e. bounds that scale with the optimal achievable cost, in batch RL. Moreover, we empirically verify that FQI-LOG uses fewer samples than FQI trained with squared loss on problems where the optimal policy reliably achieves the goal.
Originally presented at [International Conference on Machine Learning (ICML) 2024](https://icml.cc/Conferences/2024)