Meta's Muse Ember Matches Claude Haiku 5.5 at a Third of the Cost
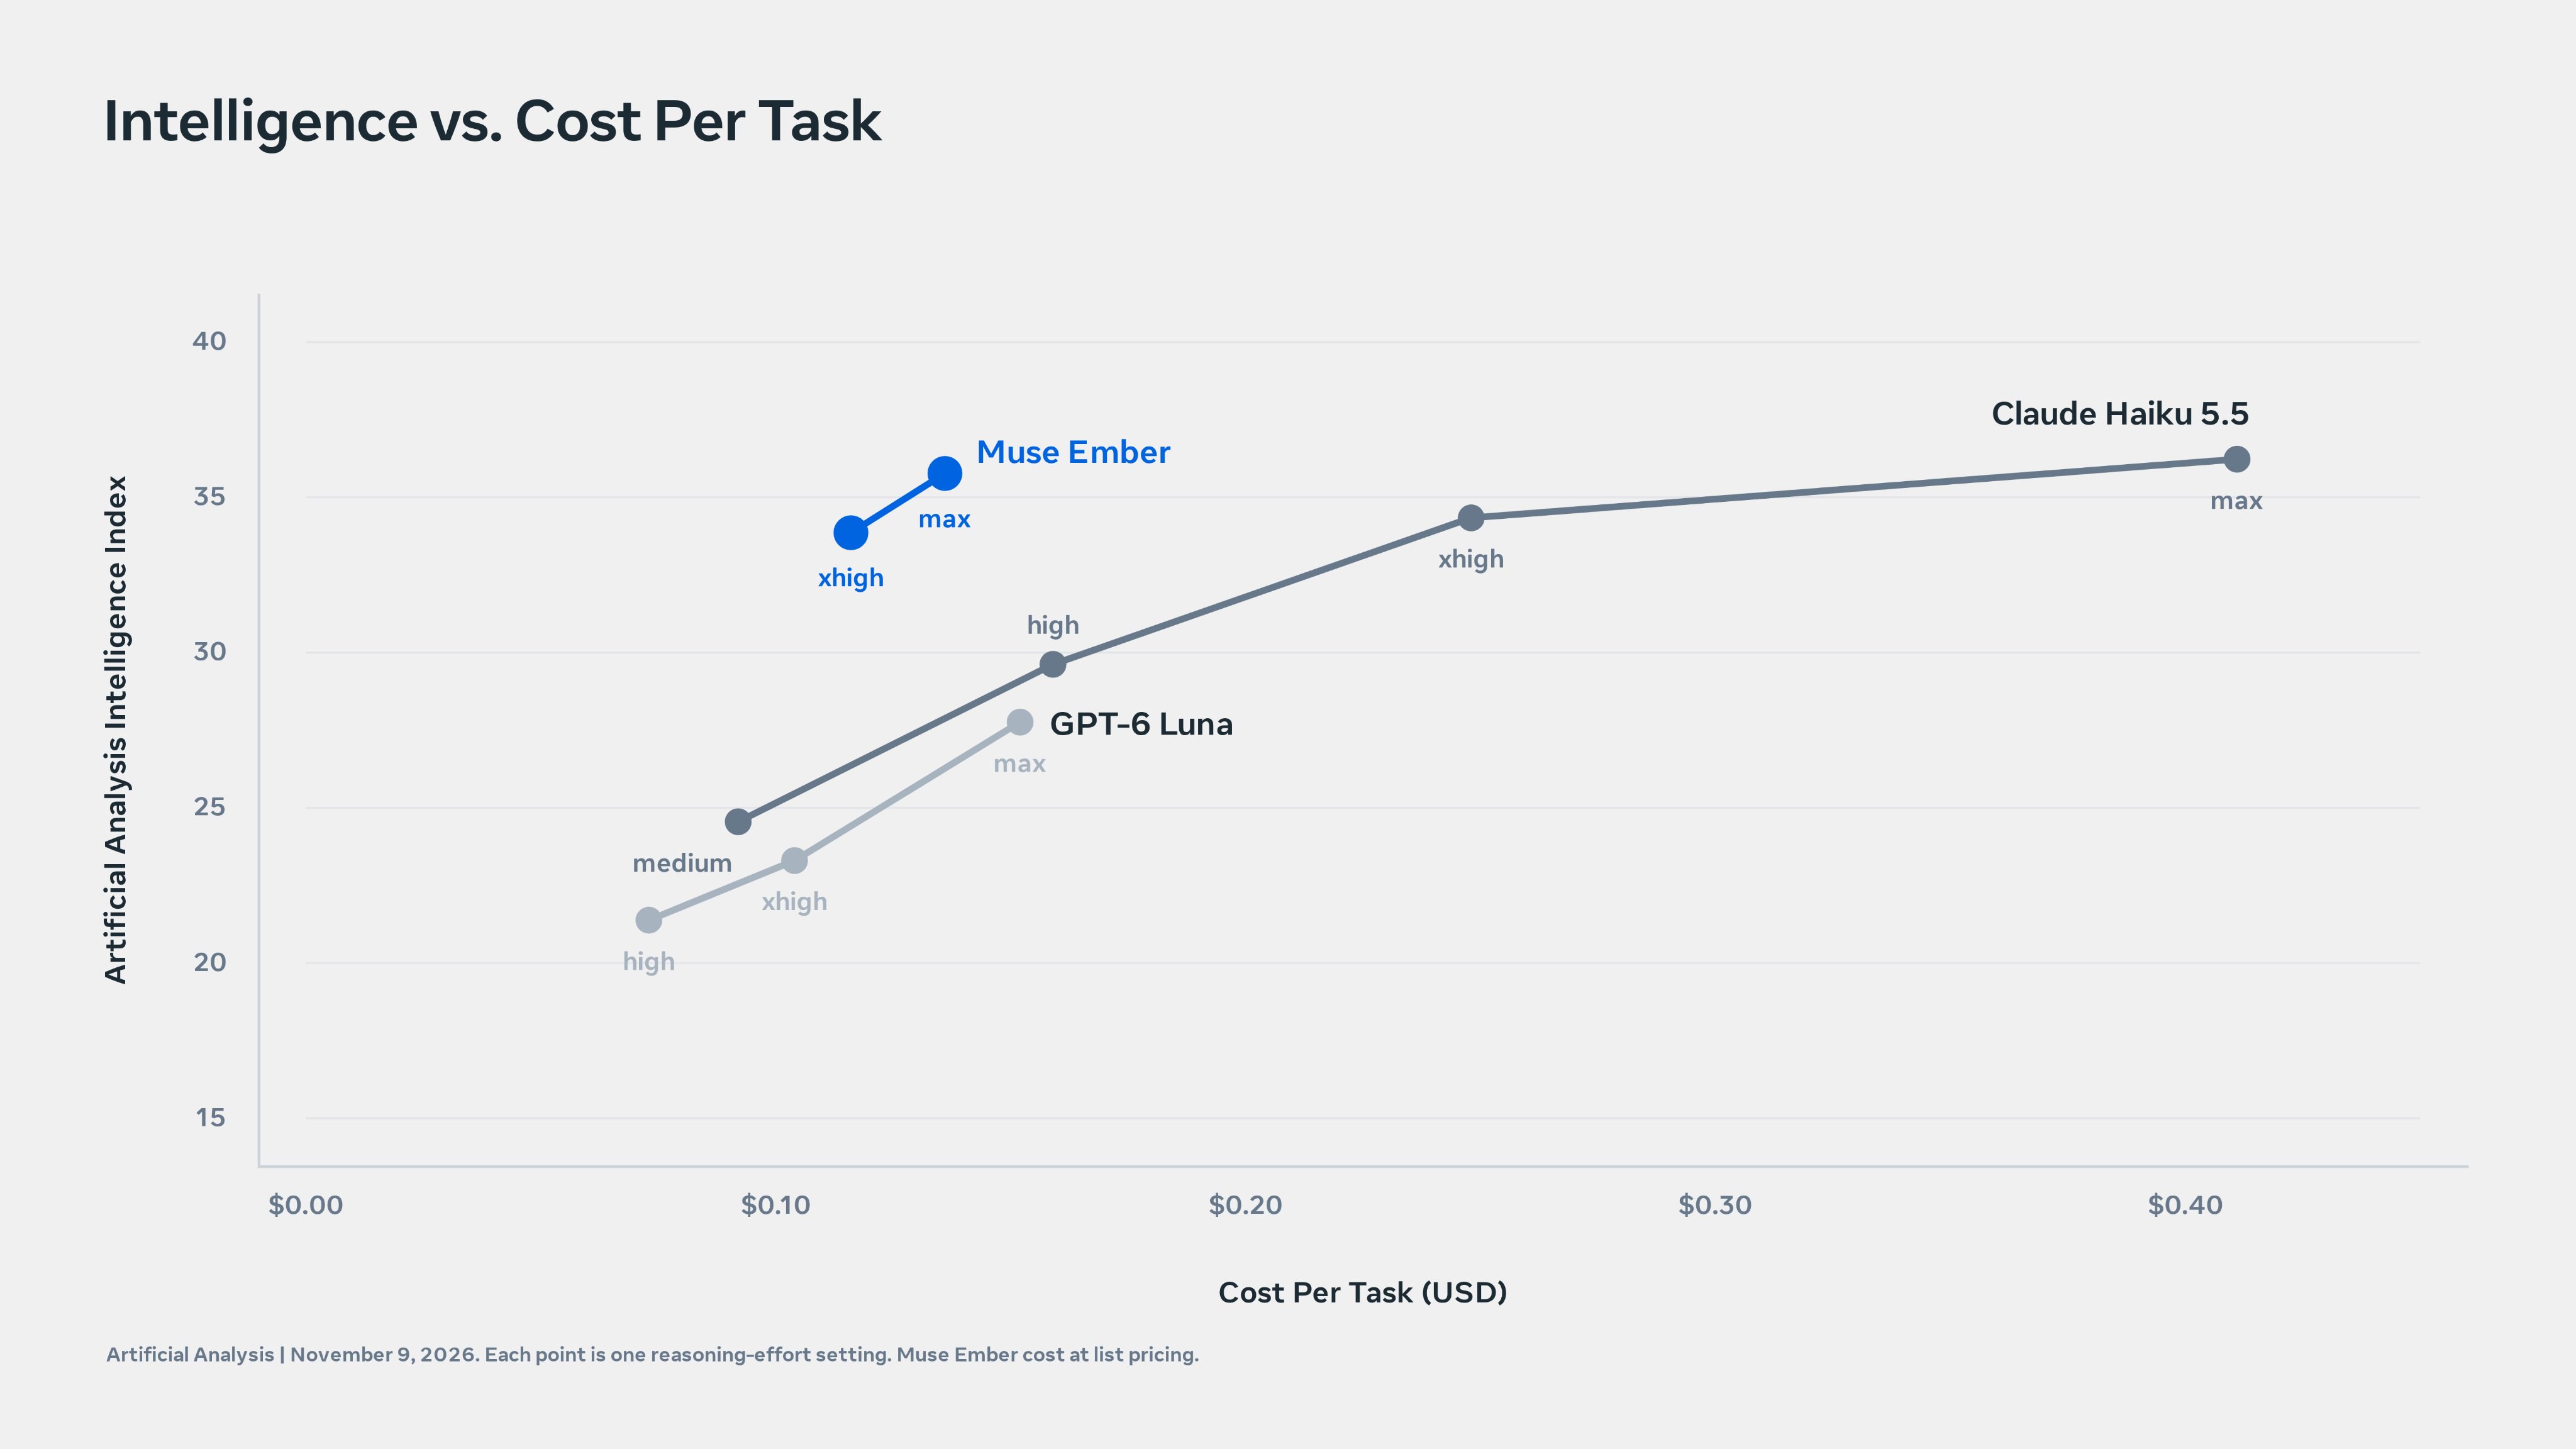
Meta's Muse Ember hits 36 on AA's Intelligence Index, tying Claude Haiku 5.5 at $0.136 vs $0.411 per task.
$0.10/$0.50 per 1M tokens, 1M context.
Meta just pushed the small-model price floor down another notch. Muse Ember is live today on the Meta Model API and Muse Code as muse-ember-1.0, at $0.10 per million input tokens, $0.004 cached input and $0.50 output.
The number that matters is on Artificial Analysis Intelligence Index v5: Ember (max) scores 36, tying Claude Haiku 5.5 (max), with GPT-6 Luna (max) at 28. But one AA task costs $0.136 on Ember versus $0.411 on Haiku 5.5. Same score, a third of the bill. Every Luna reasoning setting sits below it.
The spec sheet is built for agent pipelines: 1M-token context, up to 512K output tokens, native text, image, audio and video input, and Responses API support. Meta's positioning is blunt. Muse Wonder plans the hard problems; Ember handles the volume: tool calls, routing, extraction, long-document parsing, running tests and targeted fixes.
The more interesting part is the lineage. Ember is the first model trained using Muse Wonder Full, the first payoff of Meta's plan to distill its biggest model into specialized small ones. And it undercuts Meta's own lineup: Ember scores 36 on the AA index to Muse Spark 1.3's 37, but costs $0.14 per task against Spark's $2.39. That's 17x cheaper for one point. For good-enough subagent work, Spark just got cannibalized.
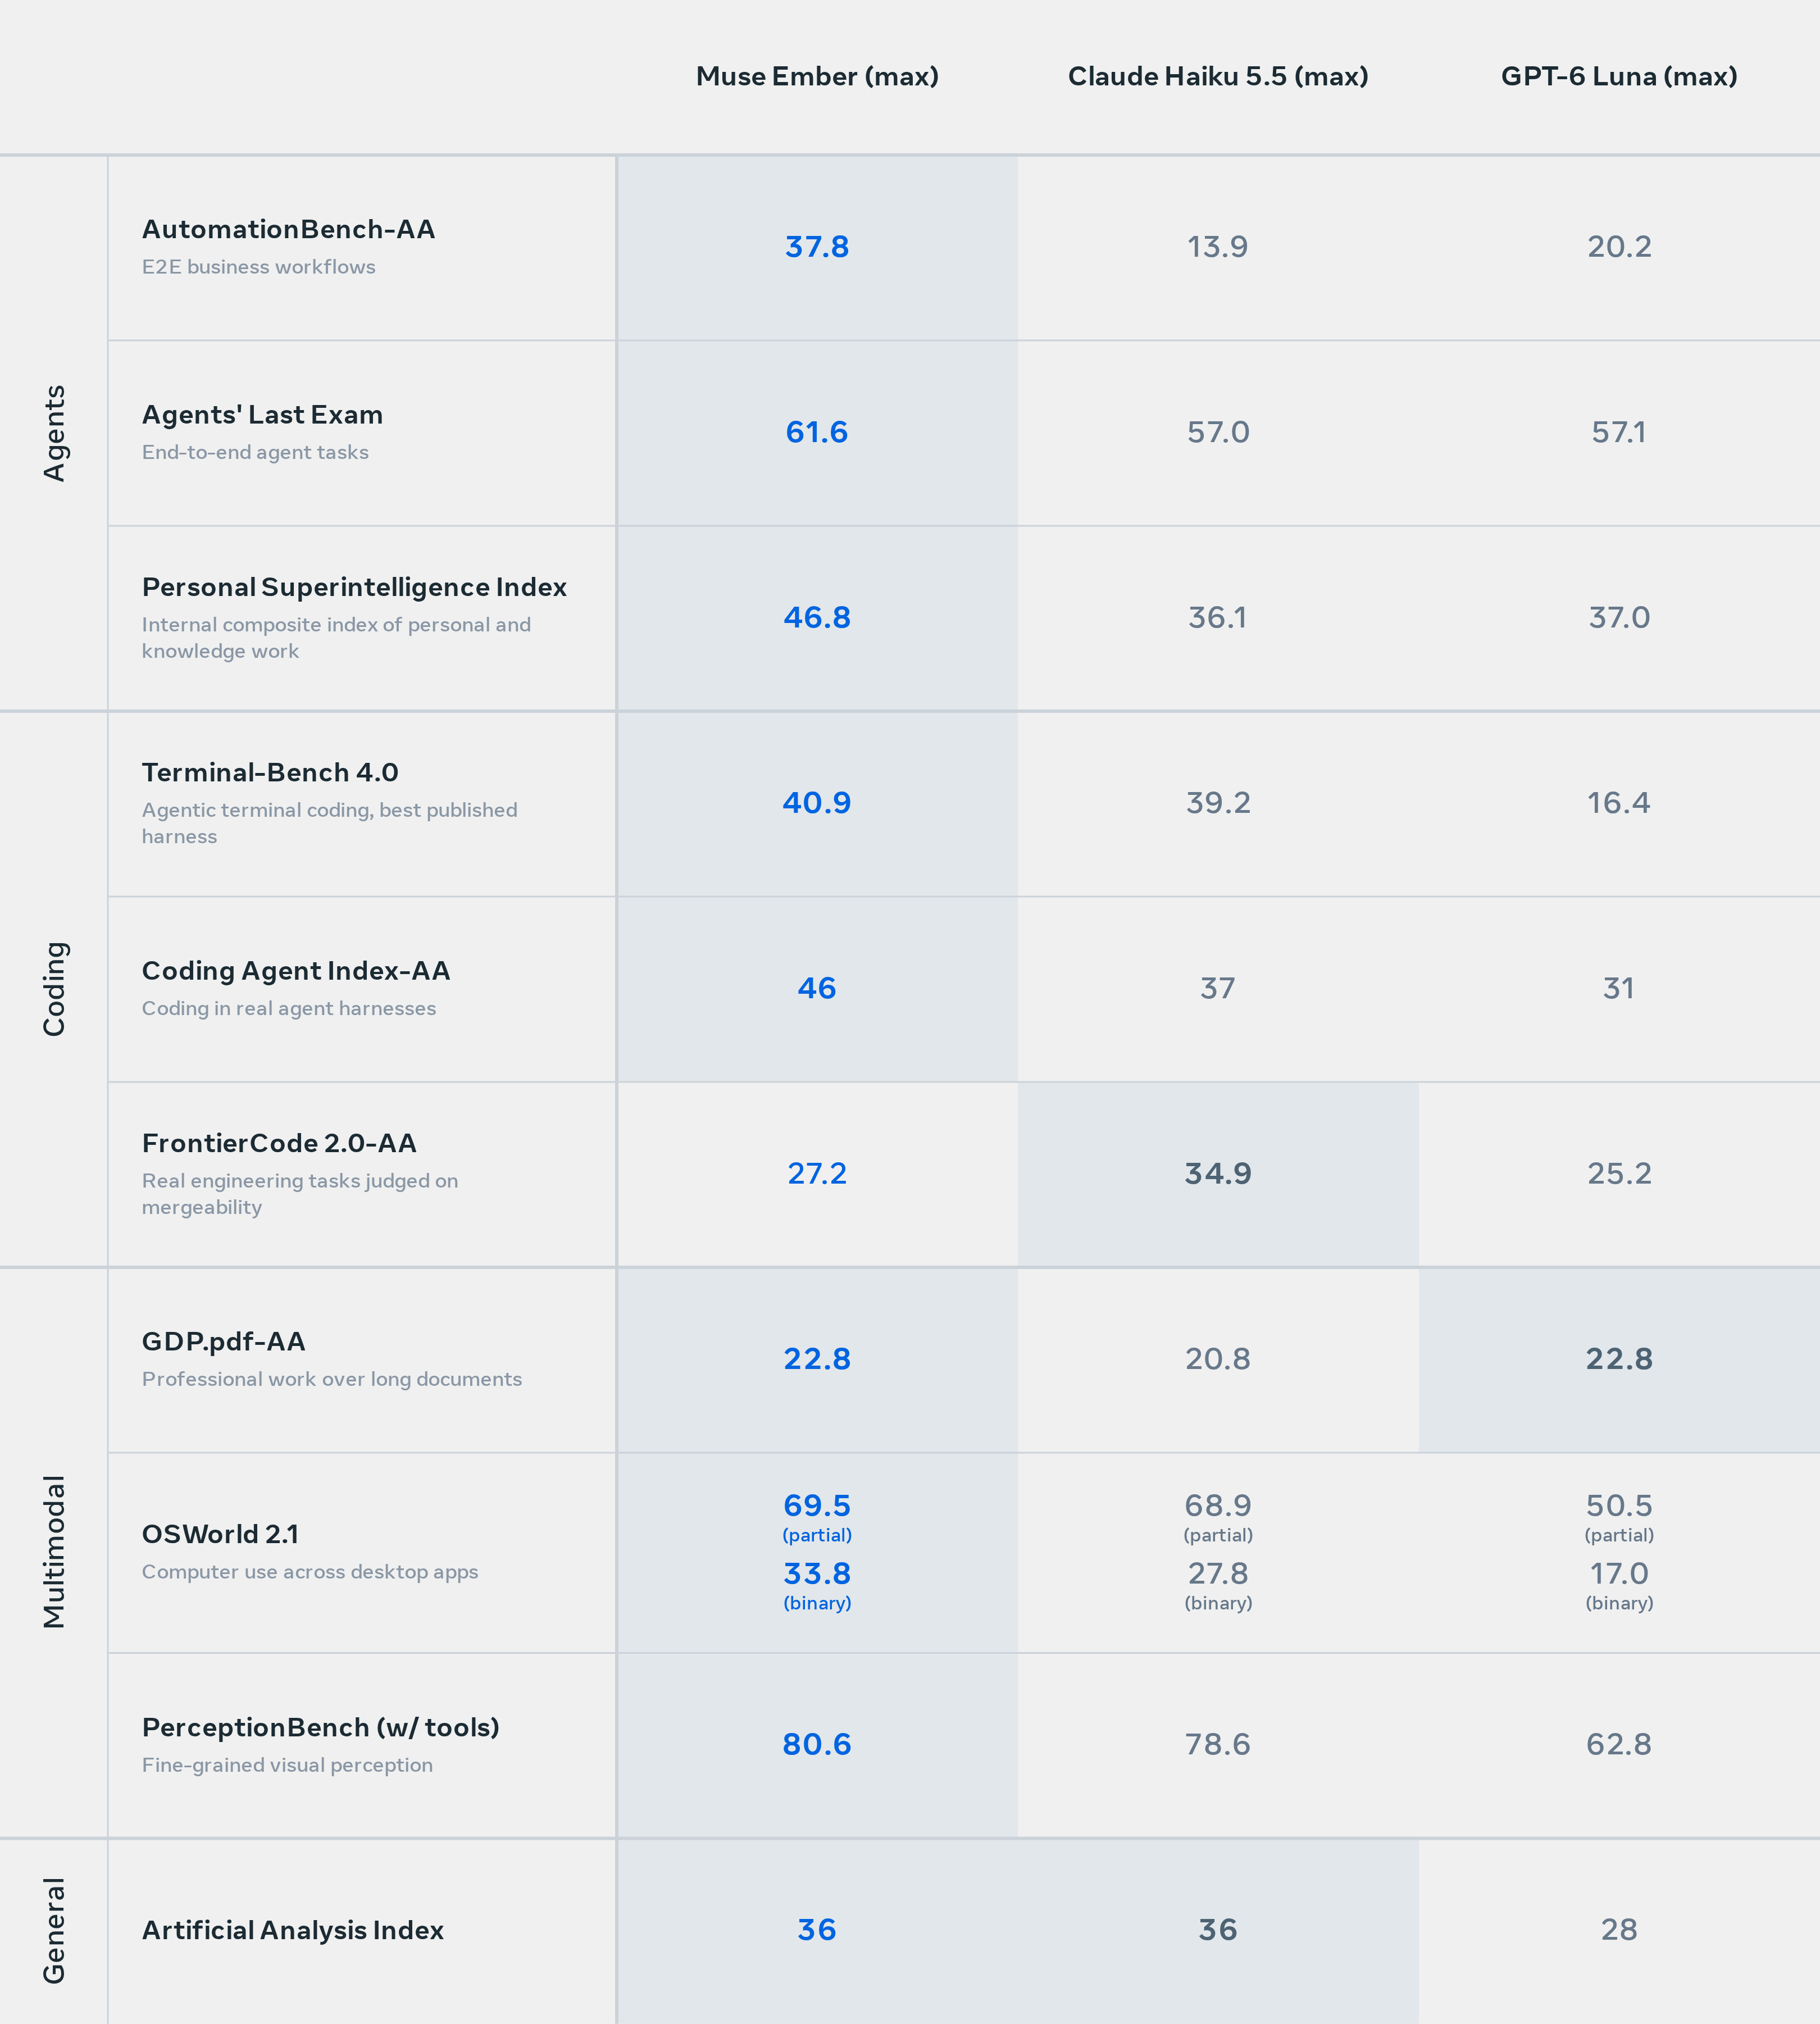
The widest gaps are on agent work: AutomationBench-AA 37.8 vs Haiku's 13.9 and Luna's 20.2; Coding Agent Index-AA 46 vs 37 and 31; Terminal-Bench 4.0 40.9 vs 39.2 and 16.4; OSWorld 2.1 binary 33.8 vs 27.8.
Don't read the table as a sweep. On FrontierCode 2.0-AA, which grades real engineering tasks on mergeability, Ember's 27.2 loses to Haiku's 34.9. Hard work still belongs to bigger models. Agents' Last Exam, PSI, OSWorld and PerceptionBench are Meta-internal evals, and Terminal-Bench compares each model in its own best harness (mini-swe-agent for Ember, Claude Code for Haiku, Codex for Luna), not like for like. Ember's cost-per-task points are also estimates at list pricing.
Early partners lead with latency. Cloudflare says tail latency ran up to 30% faster than the comparable model it tested; You.com measured a 2.2-second p95 on coding tasks, 4x to 13x faster than leading open-weight models, with 36–48% fewer output tokens. Box, Cline and Oracle are also in the launch cohort. It's API and Muse Code only; no weights.
For the past year, small models competed on how close they could get to the big ones. Ember changes the question to who's cheapest at the same score. If $0.136 a task holds up in production, the next move from Haiku and Luna won't be a higher score. It'll be a lower price.
— Nvdium Tech Editor