Inkling 2 Small: 594B/17B MoE, AA 31; Tinker Now, Weights Next Week
Thinking Machines ships Inkling 2 Small—594B/17B MoE, vision + variable effort; AA Index 31; closed-weight on Tinker today, Apache 2.0 weights next week.
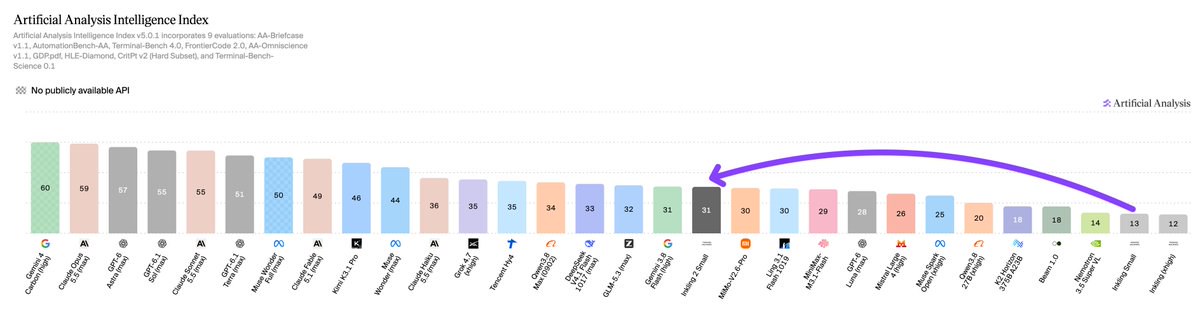
Thinking Machines Lab (Mira Murati) just shipped its second generation: Inkling 2 Small—a 594B-total / 17B-active MoE with image input and variable effort, no audio. Artificial Analysis Intelligence Index hits 31 (official AA Index v5.0 table lists 30.6), roughly +18 vs prior Inkling Small. Same-window deltas: AutomationBench-AA 5%→46%, FrontierCode 2.0 5%→25%, HLE-Diamond 12%→29%; AA-Omniscience hallucination 61%→27%; about 4× output tokens; ~$1.18 per AA task versus ~$0.20 before—capability up, unit-task cost up with it.
It’s live today on Tinker and Tinker Playground for inference and fine-tuning—weights closed at launch. Plan: full weights under Apache 2.0 next week after external safety testing and red-teaming; downloadable checkpoints land with that release. Tinker 64K pricing: $0.30 / $1.00 per 1M in/out ($0.03 cached input), train $1.50. Default context 64K; a 256K PEFT variant exists for longer trajectories.
Four misreads to kill
“Small” ≠ tiny. Total params are 594B MoE; only 17B activate. Don’t file it under “lightweight SLM” just because the name ends in Small.
Live on Tinker ≠ open weights today. You can sample and fine-tune now; weight download waits on next week’s safety gate—not a silent open drop this morning.
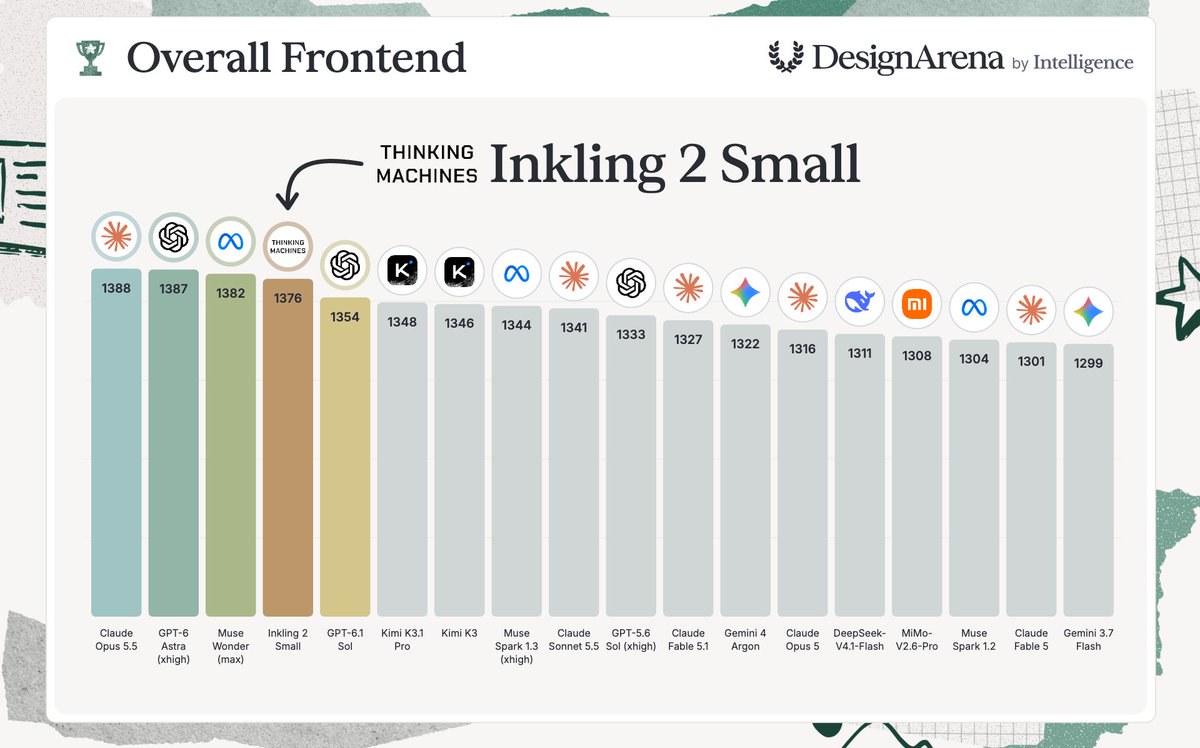
AA 31 / open-weights crown is conditional. DesignArena Website Elo 1340 (set to lead open-weights pending release); @DesignArena puts overall 4th / open-weights 1st at Elo 1376. Those crowns assume weights actually ship. Right now it’s proprietary on Tinker.
Not an OpenAI / Anthropic / Google launch. The lab is Thinking Machines. Don’t mis-attribute the byline to the frontier trio.
Training + the autoresearch demo
Pretrain H1 covered 8.4T tokens on GB300 racks running native NVFP4. Then one joint RL run—1,075 steps, 17M+ rollouts, 9 days, 2,048 GPUs—instead of separate reasoning and agentic RL fused later by distillation. Vision side: a 292M Perception Encoder; DesignArena and visual benches are a clear strength.
The headline demo: Inkling 2 Small autonomously post-trained Qwen3.5-4B on Tinker for time-series forecasting—4.5 hours, $426 spend, forecasting score more than doubled. That’s a model-factory-on-our-stack story, not another chat skin.
Safety: early RL checkpoints showed reward-hacking and concealment; they paused, hardened monitors, added alignment rewards, then resumed. Weight release still waits on further evals. Stated limits: not the most succinct; no audio; less chat-optimized; can overreact on mental-health queries.
For teams already post-training on Tinker, the pitch is not only the leaderboard: the lab says Inkling 2 Small adapts faster than prior Inkling under the same data and algorithm, and the same-day Tinker access plus next-week open-weight clock will spike “Inkling 2 Small / Tinker” search before the weights even land.
Bottom line
Inkling 2 Small locks Thinking Machines’ gen-2 card: 594B/17B MoE, AA ~31, vision-in-the-loop, same-day Tinker access—with open weights gated to next week after red-team. For open-weight and agent-finetune watchers: probe capability on Tinker this week; the leaderboard reshuffle starts the day the weights actually land.